


Why do I get a lock wait timeout or deadlock when saving, submitting or renaming?
You can see Lock wait timeout exceeded or Deadlock found when trying to get lock when you save, submit or rename a document while another transaction holds a lock on the same row. It usually happens during concurrent submits, a long-running background job, or the rename of a document that many other documents link to.
The error
You see one of these, usually in a "Server Error" dialog or in the Error Log:
pymysql.err.OperationalError: (1205, 'Lock wait timeout exceeded; try restarting transaction')
pymysql.err.OperationalError: (1213, 'Deadlock found when trying to get lock; try restarting transaction')
On MariaDB 11.6.2 and later, you can also see this during a rename or a busy save:
pymysql.err.OperationalError: (1020, "Record has changed since last read in table '<table>'")
Frappe treats all three as a deadlock, because MariaDB's newer snapshot-isolation check (error 1020) is, from the user's point of view, the same problem as error 1213.
Why this happens
InnoDB, the database engine Frappe uses, locks a row as soon as a transaction updates or inserts it, and holds that lock until the transaction commits or rolls back. If a second transaction needs the same row, it waits. By default MariaDB waits up to 50 seconds (innodb_lock_wait_timeout) before it gives up and raises error 1205. If two transactions are waiting on each other's locks at the same time, MariaDB does not wait at all: it detects the circular wait immediately, rolls one transaction back, and raises error 1213 (or, since MariaDB 11.6.2, error 1020).
Rename is a special case. Renaming a document updates its own row and then every Link or Dynamic Link field in every DocType that points to it, all inside one transaction. Renaming a document that many other records reference, for example a Warehouse, Item Group or a Workflow Action, holds locks on several tables for longer. Any other transaction that touches those same rows while the rename is running, such as a Sales Invoice being saved against that warehouse, has to wait and can time out.
Common triggers:
- Several users submitting documents that update the same linked record at the same time, for example Sales Invoices against the same Customer or Warehouse.
- A background job (a stock repost, a scheduled job, a bulk update) that holds a long transaction while a user saves a related document.
- A browser tab or an API session left open with an uncommitted change, still holding a lock.
- Renaming a document that many other documents link to.
For a background job, Frappe already retries automatically. If execute_job sees error 1205 or 1213 (or 1020, since Frappe maps it to the same deadlock check), it rolls back and retries the job up to 5 times with a growing delay. A save or submit from the desk is not retried automatically — the user sees the error right away.
How to fix it
- Open System Console (search for it in the top search bar). You need the System Manager role.
- Under Database Processes, turn on Show Processlist. The table fills in without needing to click Execute, and shows every open database session, its state and how long it has been running.
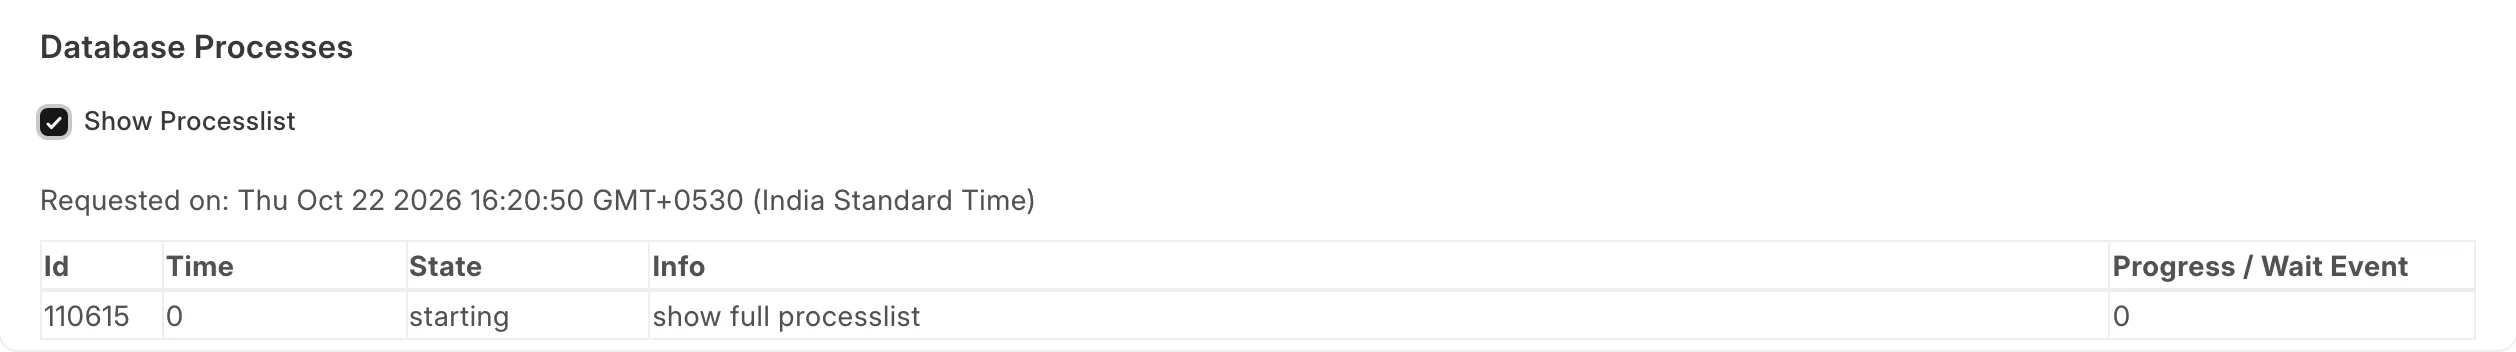
- Look for a session whose State is not idle, or whose Time is high. Its Info column shows the query it is running, or is blank if it is an open transaction waiting on something else.
- For the full detail of a deadlock, including which table and row caused it, run
SHOW ENGINE INNODB STATUS\Gfrom a database console (bench --site <site-name> mariadb) and read the LATEST DETECTED DEADLOCK section. - If a session is stuck holding a lock, end it from the same database console:
KILL <Id>;
using the Id from the processlist. On Frappe Cloud, you cannot run KILL yourself; raise a support ticket with the processlist output instead.
6. If the blocking session belongs to a background worker, restart the workers instead of killing the database session directly: bench restart. If only the scheduler is stuck, bench scheduler resume --site <site-name> brings it back without a full restart.
7. Retry the save, submit or rename.
How to prevent it
- Background jobs retry automatically up to 5 times on a deadlock or lock wait timeout, so a one-off error during a busy period usually clears on its own. Step in only if it still fails after that, or if a user is blocked immediately in the desk.
- Rename a document that many records link to (a Warehouse, Item Group or Cost Center) outside busy hours.
- In a custom script or report, commit in smaller batches instead of looping over thousands of records inside one transaction.
- Close browser tabs or API sessions you leave idle with an unsaved or uncommitted change.
If you are on an unsupported version
If your App Versions show Frappe or ERPNext v14 or earlier, upgrade. In several of these tickets the real cause was a slow query or locking behavior that newer versions have since fixed, and end-of-life versions are out of scope for a performance investigation.
If this does not fix it
If the error keeps happening outside of busy, concurrent use, raise a support ticket with the exact error text, the document you were saving, submitting or renaming, your App Versions, and the processlist output (or the System Console screenshot) from when it happened.